ORA: Open Robot-Use Agents
2026
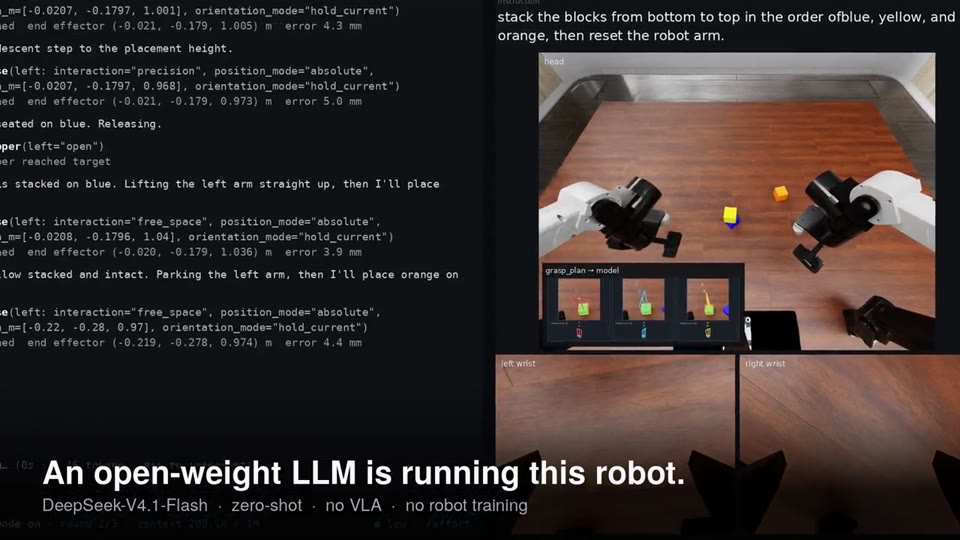
ORA lets open-weight LLMs operate robots zero-shot through perception and motion tools, with no VLA and no robot training.
Bringing LLMs into the physical world
I'm a first-year PhD student at UC San Diego, advised by Prof. Hao Zhang. I work on getting LLMs to act in the physical world. Right now I'm building ORA, an open harness that lets language models operate robots.
Two things I want to build:
Before UCSD, I did my Master's at Zhejiang University with Prof. Yiyi Liao, working on 3D and video generation, and collaborated with Prof. Andreas Geiger. I was also a research intern with Prof. Jun Gao at the University of Michigan, and got my B.Eng. from Hangzhou Dianzi University in 2022.
2026
ORA lets open-weight LLMs operate robots zero-shot through perception and motion tools, with no VLA and no robot training.
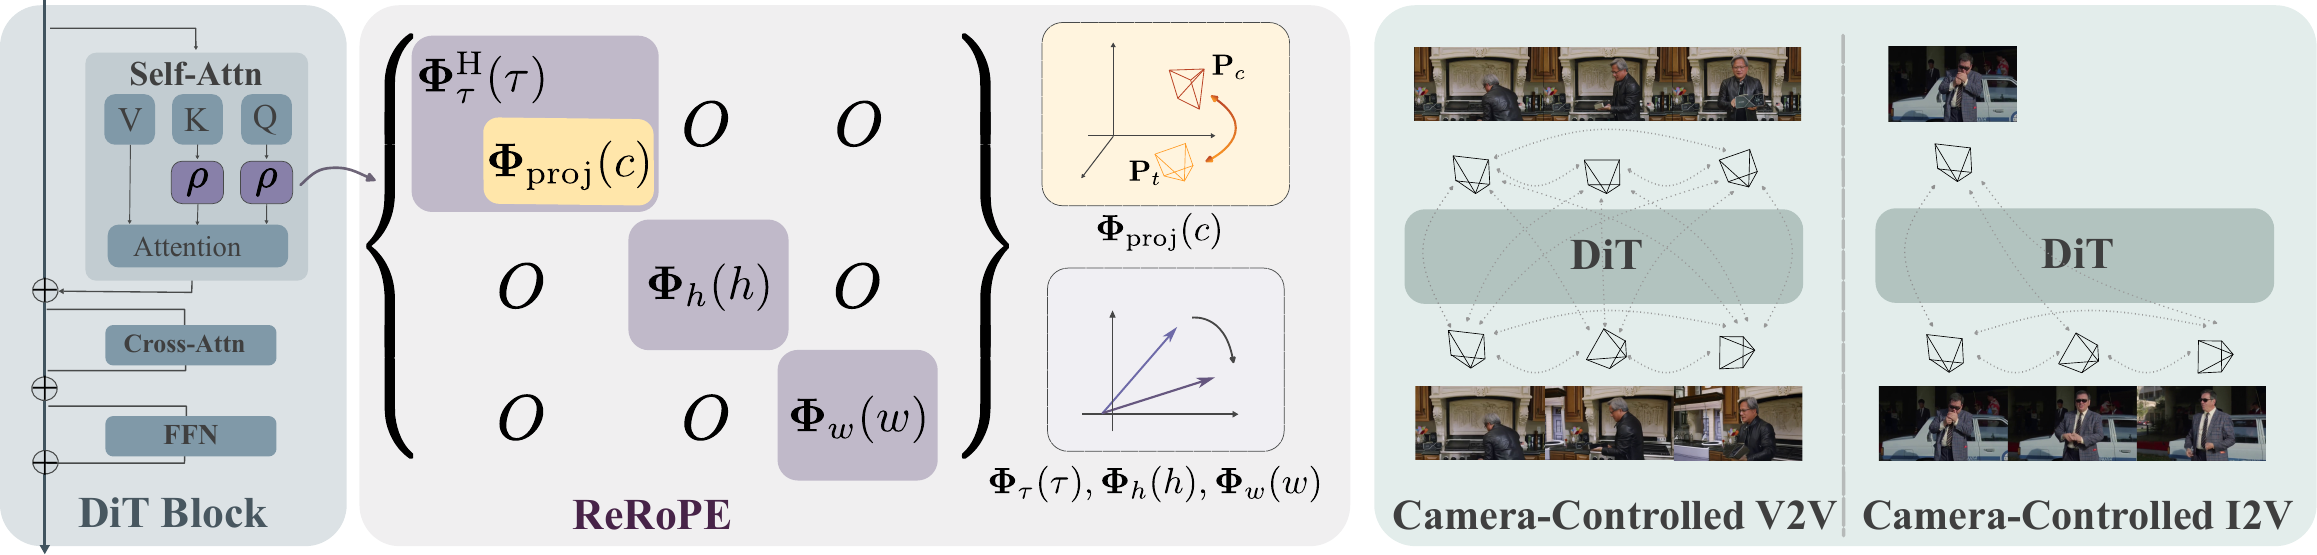
SIGGRAPH 2026
ReRoPE repurposes Rotary Position Embedding for shift-invariant relative camera control in video generation.
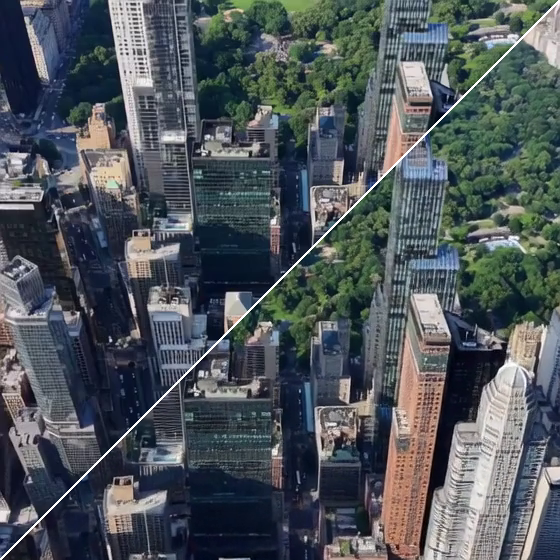
CVPR 2026
Gen3R combines feed-forward reconstruction models with video diffusion models to generate 3D scenes.
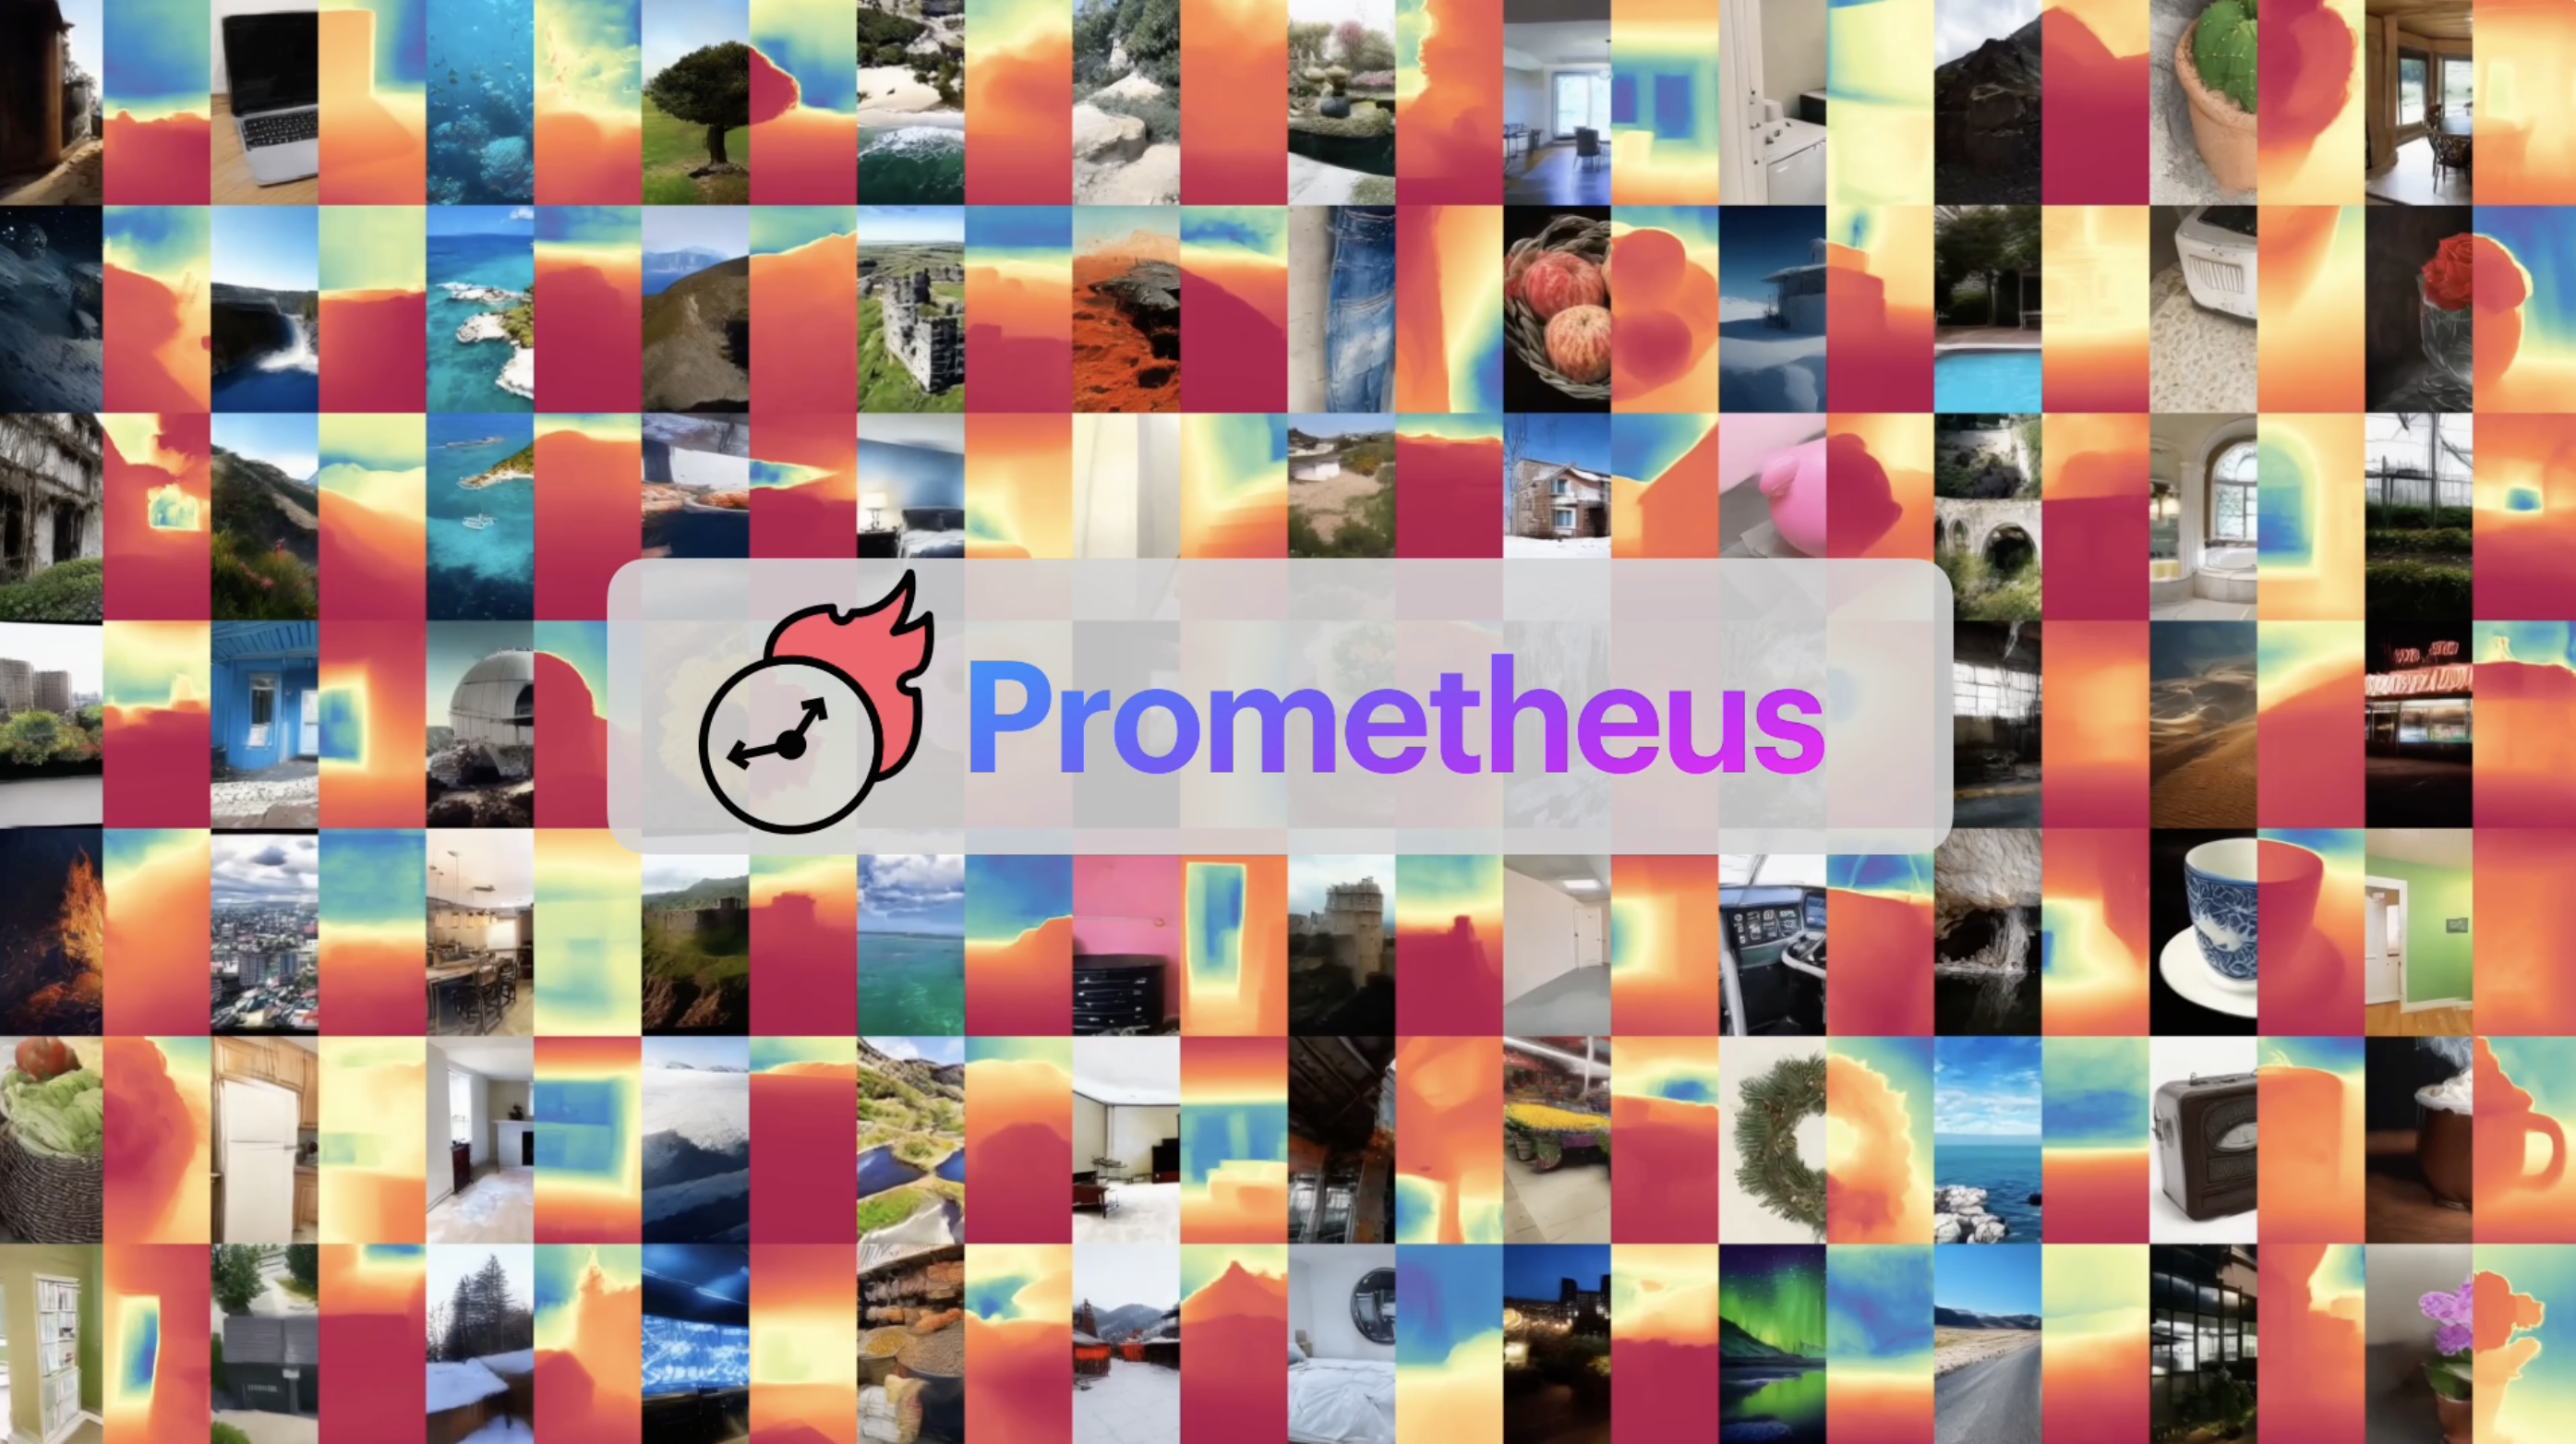
CVPR 2025
Prometheus generates 3D scenes from text in seconds, building on pretrained 2D diffusion models.
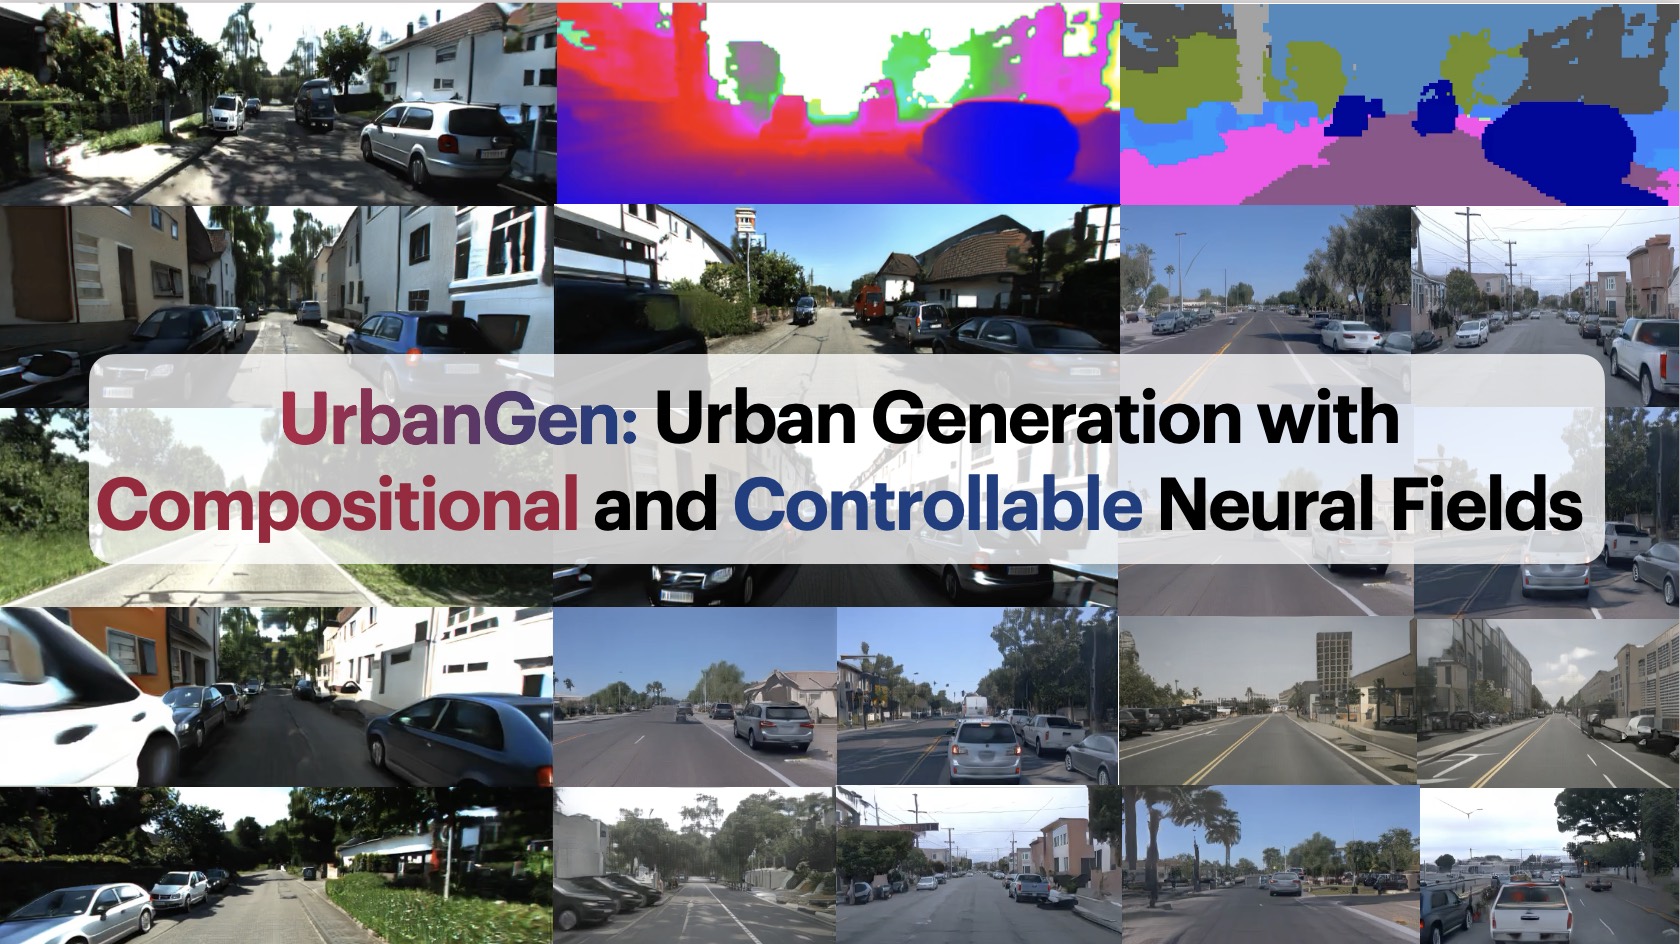
T-PAMI 2025
UrbanGen generates controllable 3D city scenes with realistic rendering and geometry.
CVPR 2025
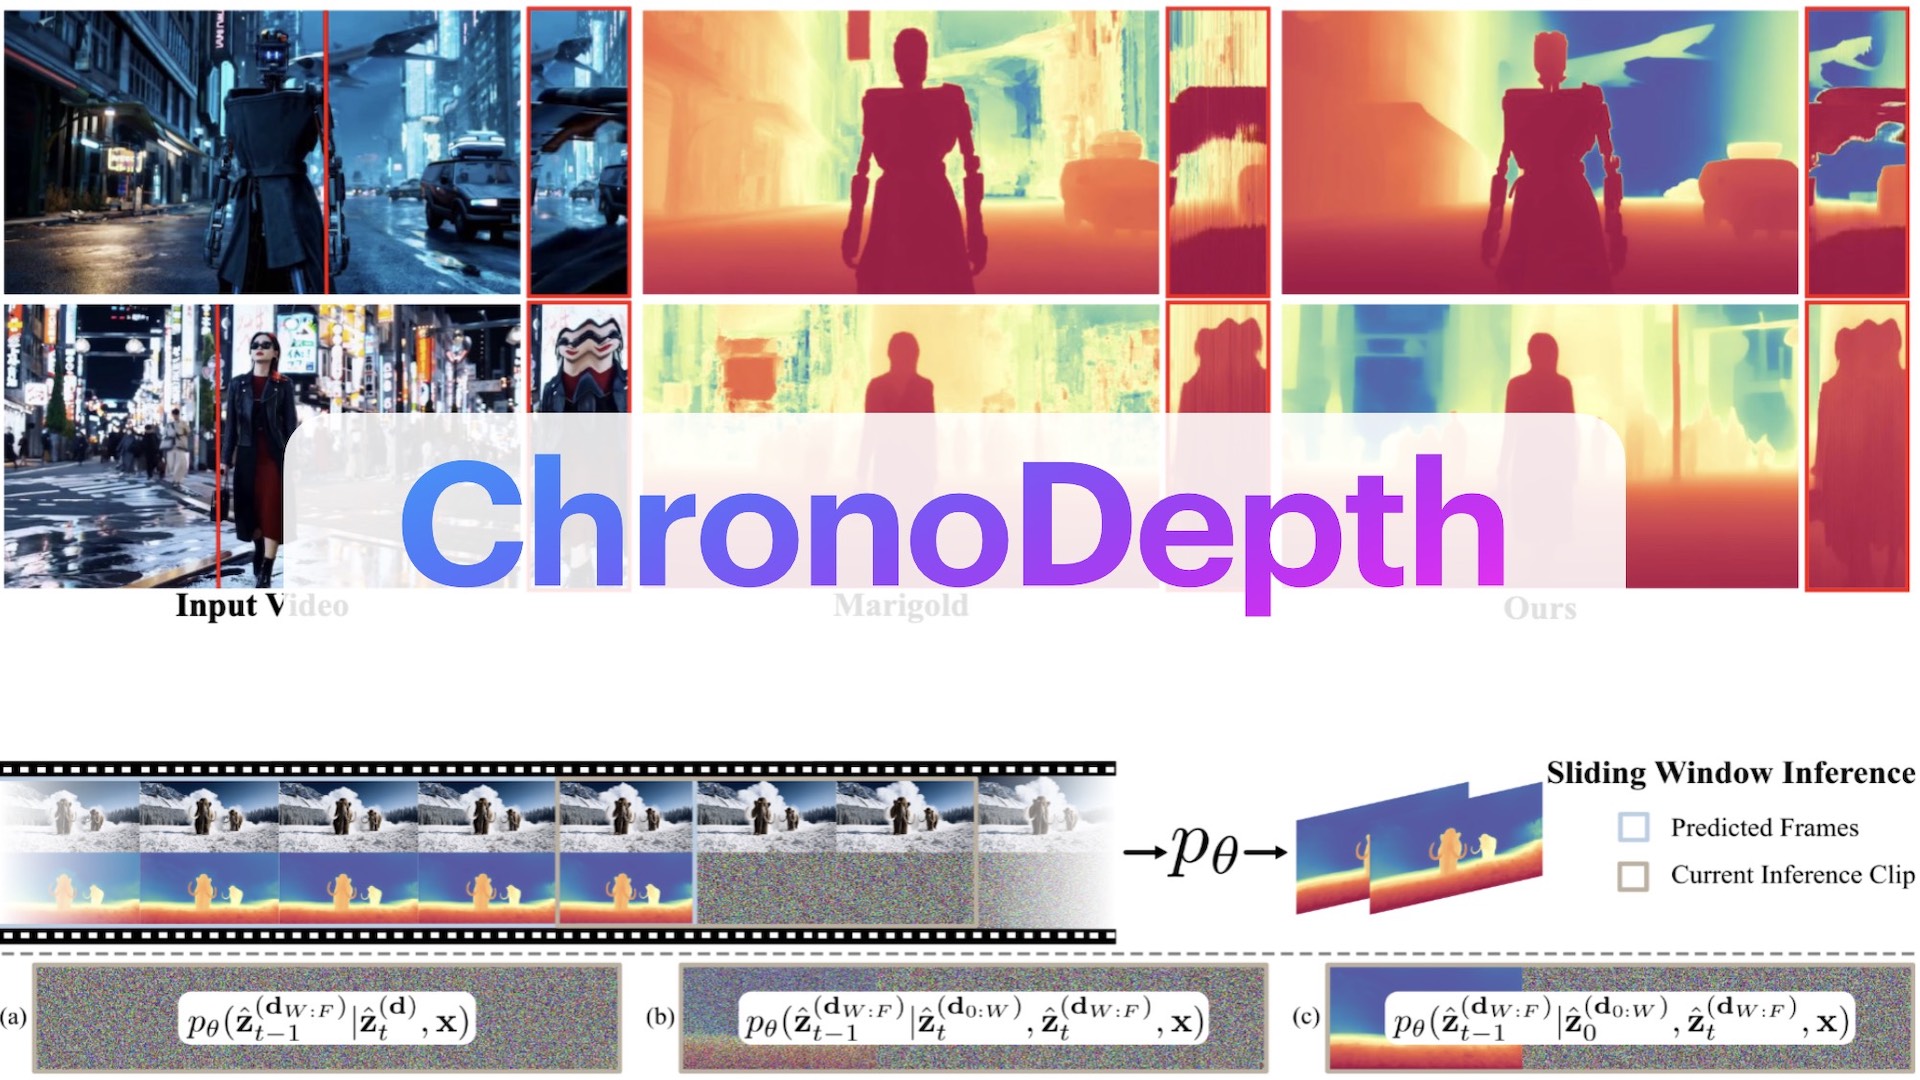
ChronoDepth uses video diffusion priors to estimate temporally consistent video depth.
NeurIPS 2025
Orientation Matters addresses orientation alignment in 3D generative models.
arXiv 2025
HeFT uses pretrained video diffusion models for zero-shot point tracking.
arXiv 2025
The Constant Eye benchmarks appearance robustness under OOD conditions in autonomous driving.
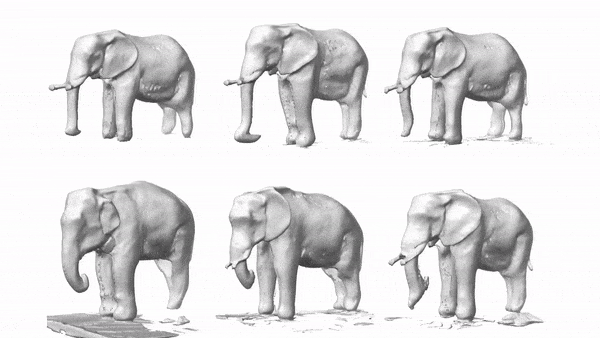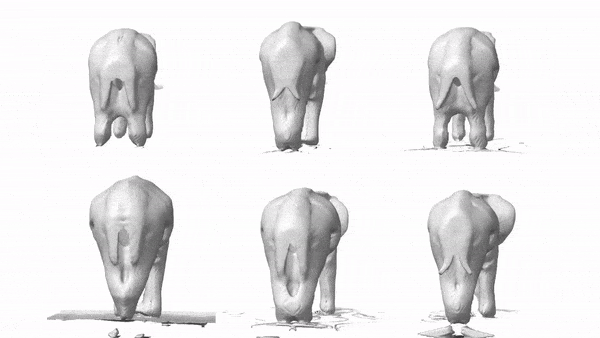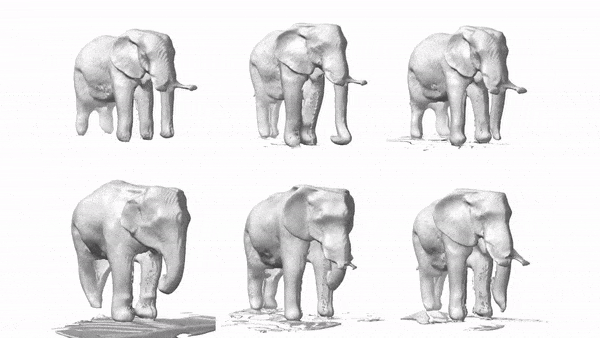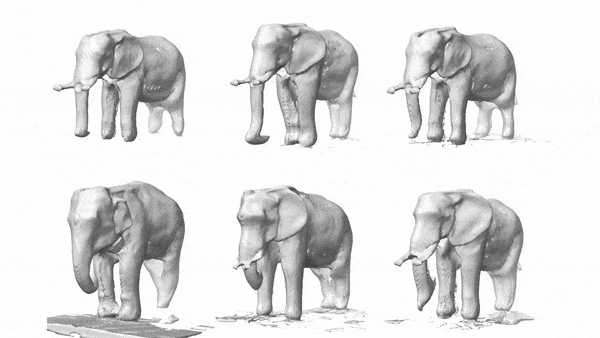
ECCV 2024 (Oral)
TeFF learns 3D-aware GANs from unposed images via on-the-fly pose estimation with a learned template feature field.
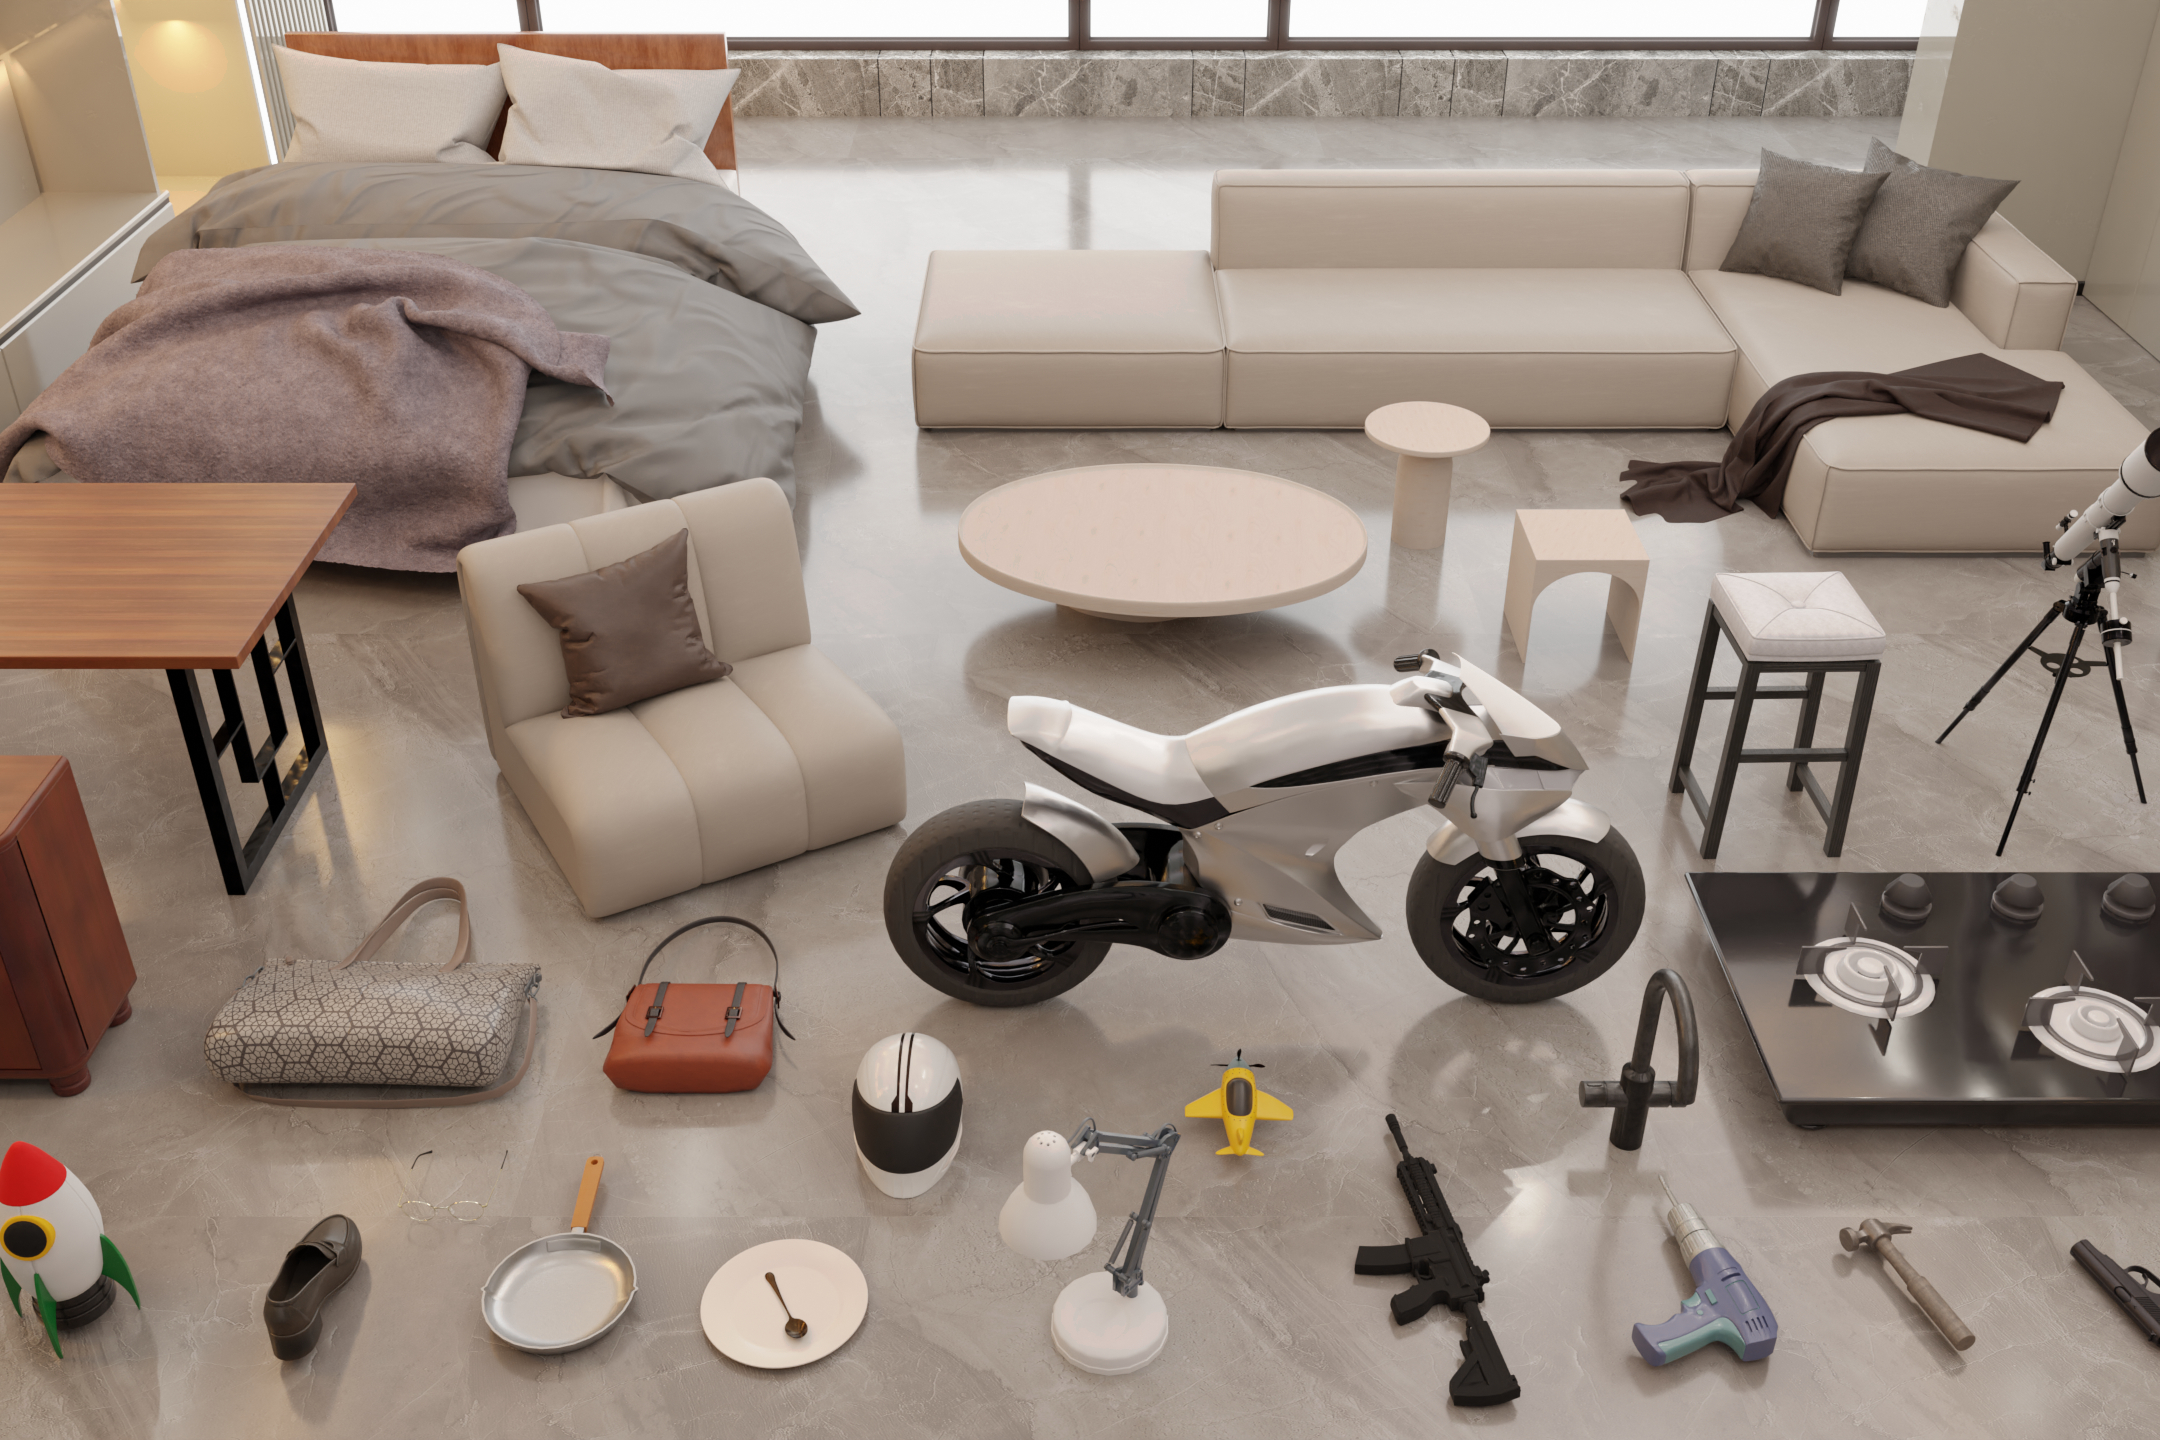
SIGGRAPH 2024
MaPa creates segment-wise procedural material graphs for high-quality rendering with significant editing flexibility.
ICCV 2023
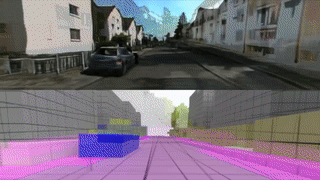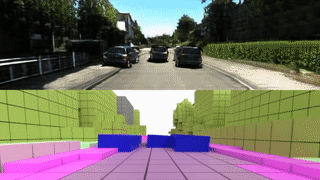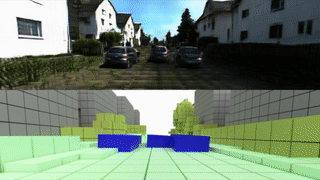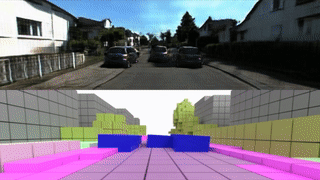
UrbanGIRAFFE uses coarse 3D panoptic layouts to guide a 3D-aware generator for controllable urban scenes.